Are You Learning Biological Signal or Shortcuts? Auditing and Mitigating Bias in Protein-Protein Interaction Datasets is now available at arXiv at https://doi.org/10.48550/arXiv.2609.10193.
We systematically characterize both reported and, to our knowledge, previously unreported biases in PPI datasets that lead machine learning models to learn shortcuts instead of biological signal. We show that even when train-test protein overlap is removed, the resulting datasets still retain usable shortcuts stemming from self-interactions, taxonomic identity, and functional relatedness. To detect and mitigate these biases, we provide an open Nextflow pipeline that combines similarity-aware, data-loss-minimizing dataset splitting with bias-minimizing negative sampling, both formulated as integer linear programs. Its key concept of quantifying biases to minimize them through optimization-based negative sampling can, in principle, be extended to any machine learning problem where the pool of negative candidates is much larger than the positives and is thus of interest also beyond PPI prediction.
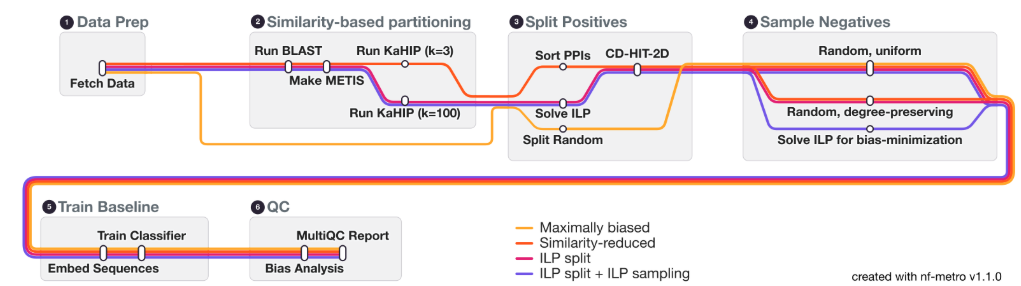
Are You Learning Biological Signal or Shortcuts? Auditing and Mitigating Bias in Protein-Protein Interaction Datasets is now available at arXiv at https://doi.org/10.48550/arXiv.2609.10193.
We systematically characterize both reported and, to our knowledge, previously unreported biases in PPI datasets that lead machine learning models to learn shortcuts instead of biological signal. We show that even when train-test protein overlap is removed, the resulting datasets still retain usable shortcuts stemming from self-interactions, taxonomic identity, and functional relatedness. To detect and mitigate these biases, we provide an open Nextflow pipeline that combines similarity-aware, data-loss-minimizing dataset splitting with bias-minimizing negative sampling, both formulated as integer linear programs. Its key concept of quantifying biases to minimize them through optimization-based negative sampling can, in principle, be extended to any machine learning problem where the pool of negative candidates is much larger than the positives and is thus of interest also beyond PPI prediction.